
Create an API key
Create the credentials you need to call the Behavioral Signals API
Every request to the Behavioral Signals API is authenticated with an API key. A key is a pair of values:
- a Client ID — a unique identifier, referred to as
cidthroughout this documentation and used in the request path - a Token — the secret used to authenticate the request, sent in the
X-Auth-Tokenheader
You can create more than one key and revoke any of them individually, so it is good practice to use a separate key per integration.
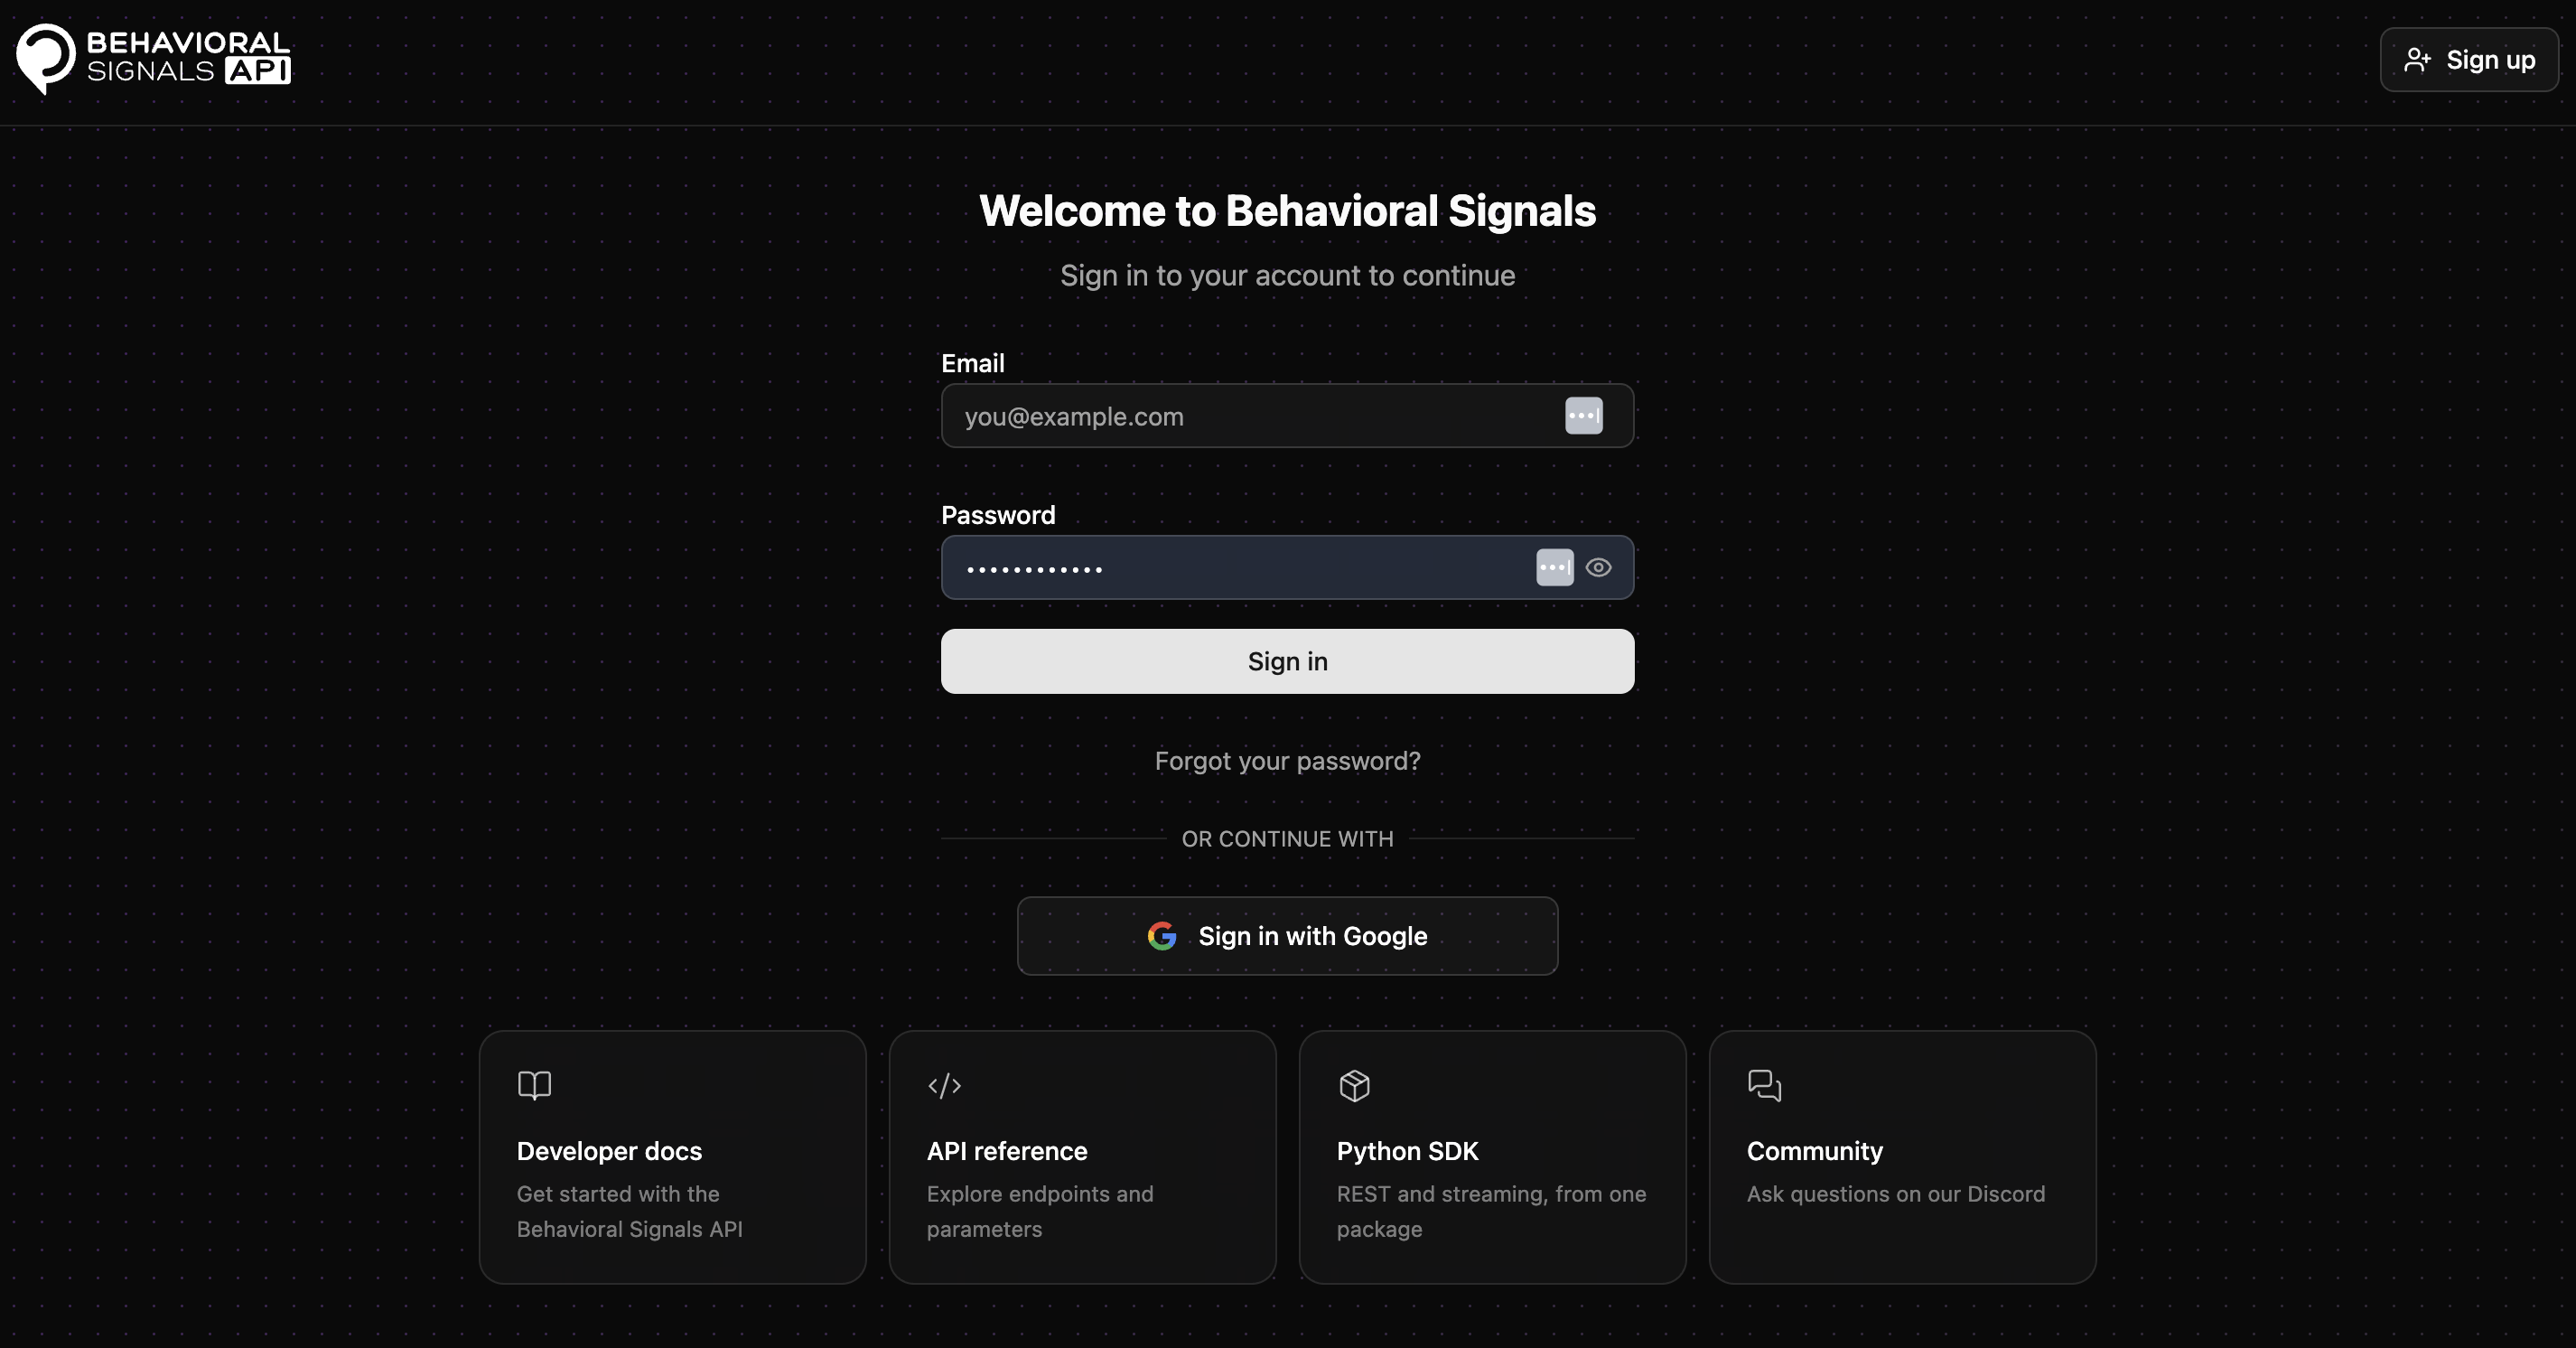
Step 1: Log in to the console
Visit https://portal.behavioralsignals.com and log in with your credentials.
Step 2: Open the API Keys page
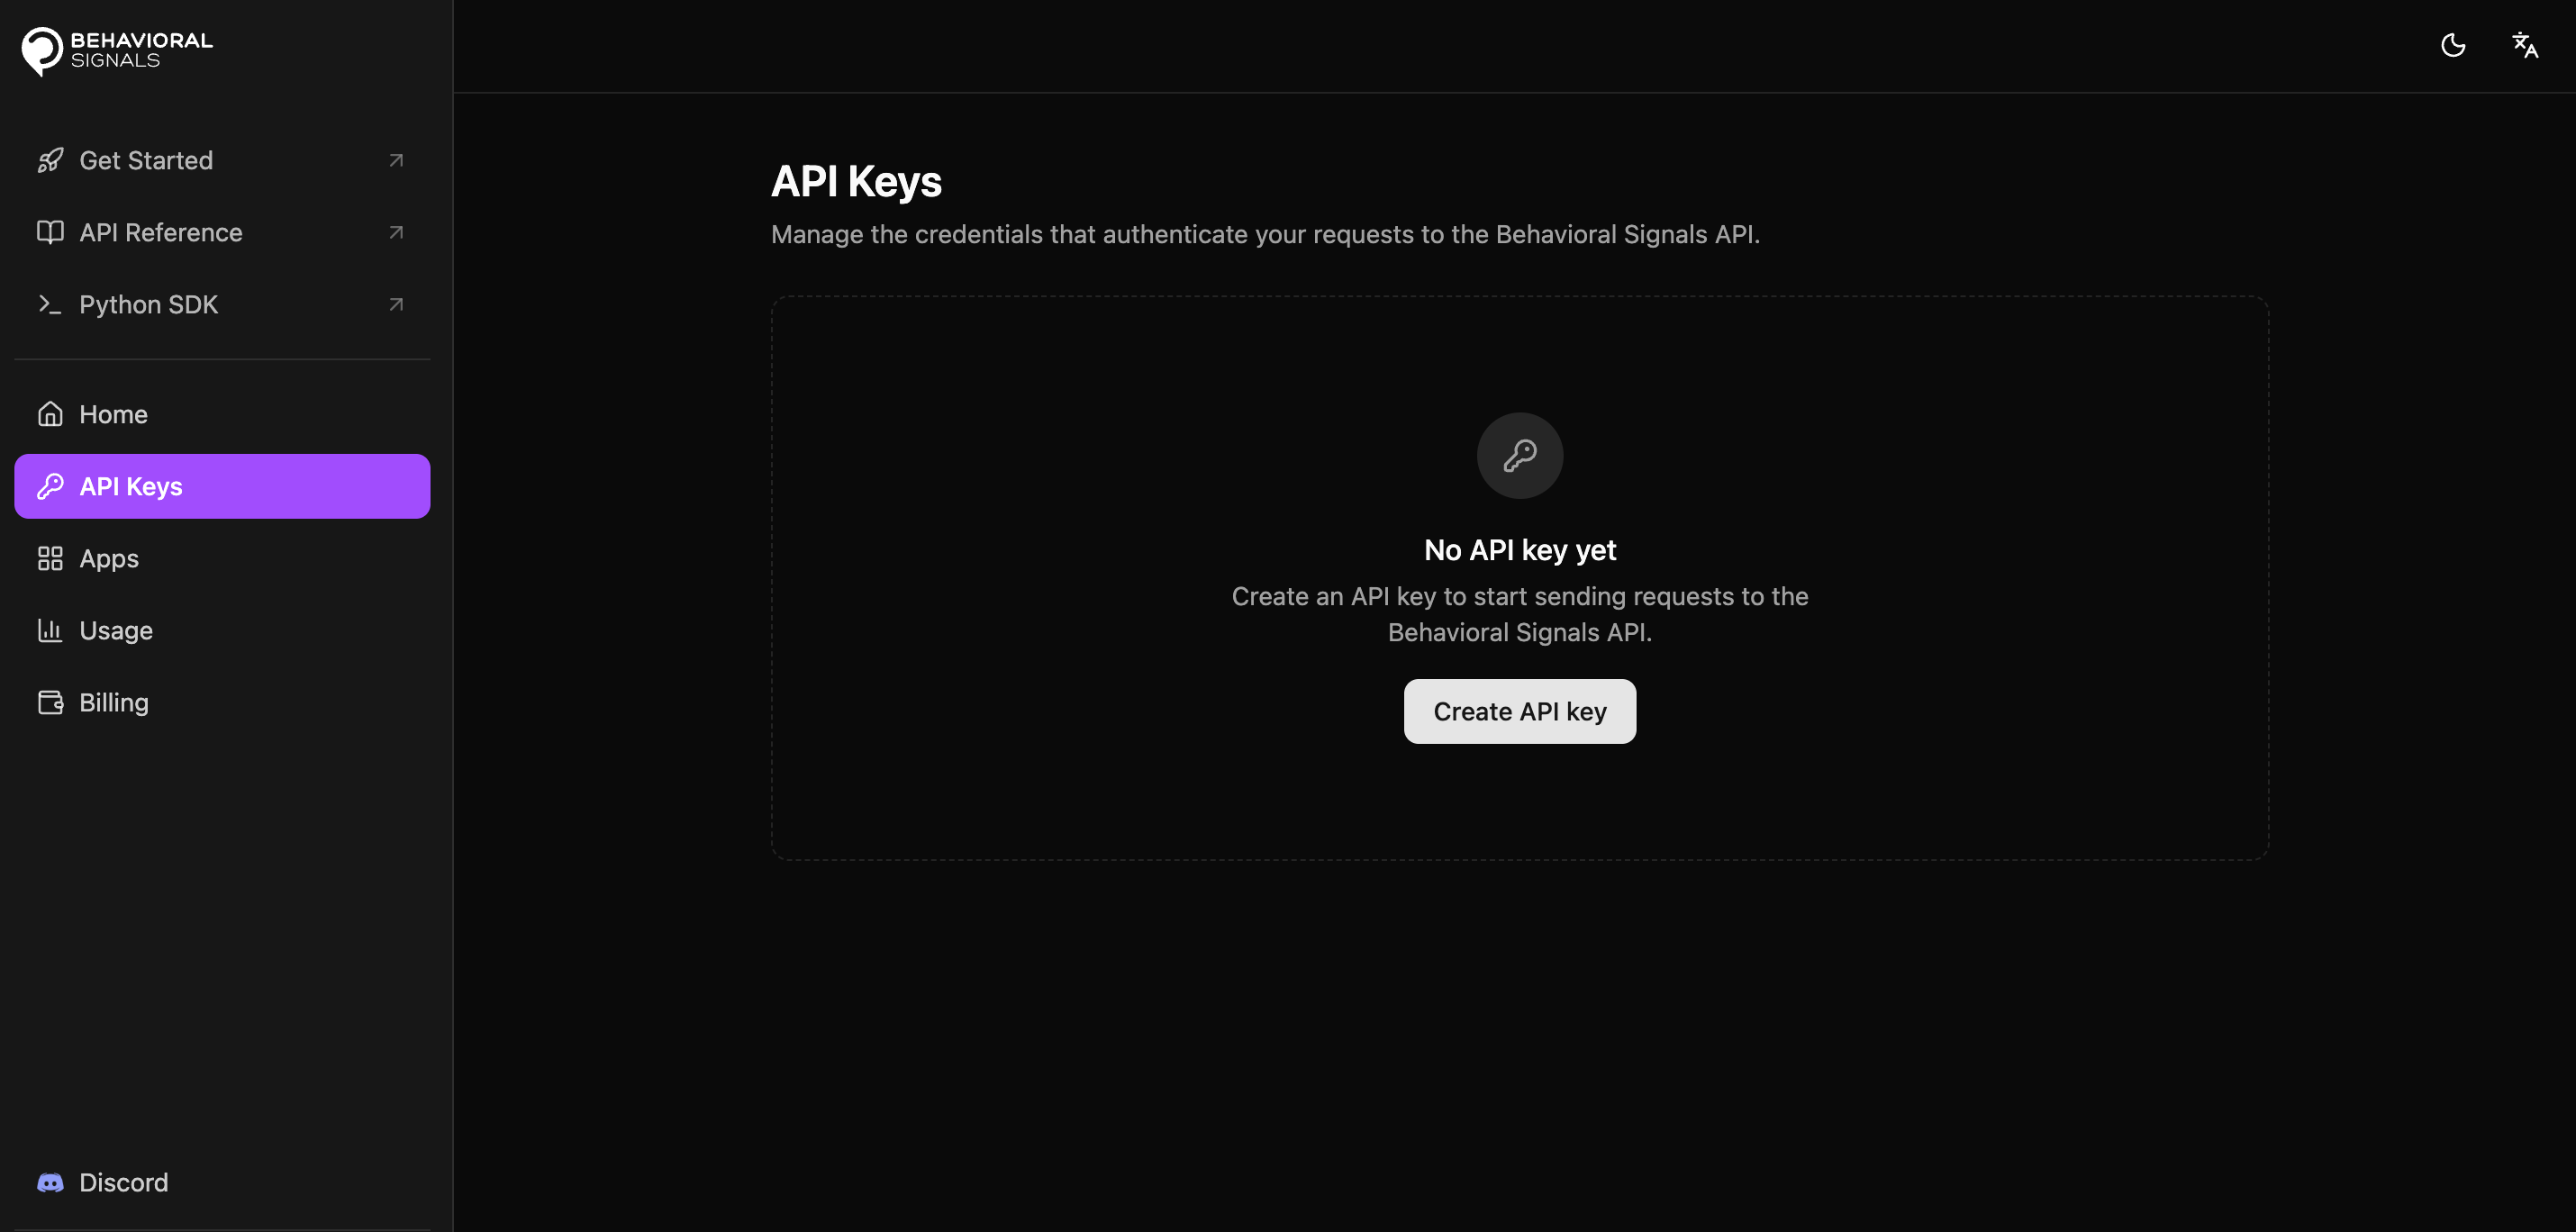
Select API Keys from the sidebar. This page lists every key on your account, with its Client ID and the date it was created.
Step 3: Create a key
Click Create API key. The new key appears in the table immediately.
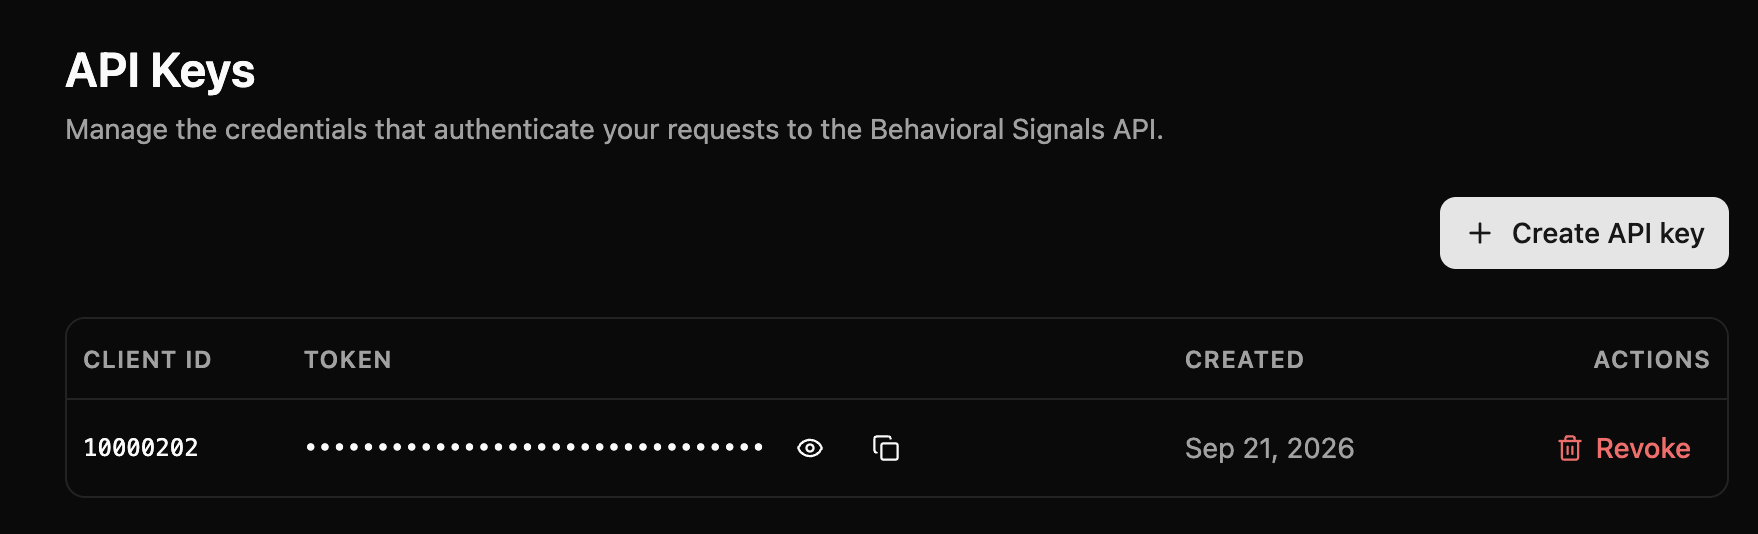
Use Reveal to display the token and Copy to put either value on your clipboard. Treat the token like a password: anyone holding it can send audio and spend your credit.
If a key is ever exposed, click Revoke. Revocation takes effect immediately and any integration still using that key will stop working, so create a replacement first.
Important for existing usersVersion 5.0.0 introduced significant changes to the output schema and internal processing. Credentials issued before that version cannot be used to send new audio. If yours predates it, create a new API key using the steps above.
API Modes: Batch & Streaming
With your key in hand, you can start sending audio for analysis using one of the two available API modes: Batch or Streaming. Both modes support Behavioral Predictions and Deepfake Detection.
🔁 Batch API (Asynchronous)
The Batch API is designed for analyzing pre-recorded audio files (in .wav/.mp3 format). Deepfake Detection also accepts video files as an experimental feature. Essentially the workflow is:
- Use the API to submit audios for processing
- Check processing status via polling
- Retrieve final prediction results once analysis is complete
This mode is easy to use and integrates well with existing audio workflows. You can learn more in the next pages of this documentation.
🔄 Streaming API (Real-Time)
The Streaming API is designed for real-time processing of audio data. Using bidirectional gRPC, you can send live audio chunks and receive predictions back with minimal latency.
- Send audio in real time (e.g., from microphone input)
- Receive immediate prediction results as audio streams in
- Ideal for conversational interfaces, call centers, and live analysis tools
Streaming supports both Behavioral and Deepfake tasks, with results delivered incrementally during the session. Visit the Streaming API section of the documentation for more.
Updated 8 days ago